Python examples
Runnable Python samples for screenshots, HTML input, JSON answers, retries, signed links and background jobs, using requests and the standard library.
Install the requests package once with pip install requests. Then save this as basic.py and run it with python basic.py.
import requests

response = requests.get(
    "https://curlshot.com/api/v1/screenshot",
    params={"access_key": "YOUR_ACCESS_KEY", "url": "https://example.com"},
    timeout=120,
)
if not response.ok:
    raise SystemExit(response.json()["error_message"])

with open("example.png", "wb") as f:
    f.write(response.content)
print("Saved example.png")Saved example.png
Every sample on this page is a complete file. They work on Python 3.8 and newer.
requests encodes the params for you. So you can write the page address as it is, even when it contains & or ?.
The timeout=120 is how long your own code waits for an answer, in seconds. The API's own timeout option can be as long as 90 seconds, so give your code more than that.
#Add options
Each option is one more entry in params. Here the access key goes in the X-Access-Key header, which keeps it out of the address.
import requests

response = requests.get(
    "https://curlshot.com/api/v1/screenshot",
    headers={"X-Access-Key": "YOUR_ACCESS_KEY"},
    params={
        "url": "https://en.wikipedia.org/wiki/Eiffel_Tower",
        "viewport_device": "iphone_15_pro",
        "full_page": "true",
        "block_cookie_banners": "true",
        "format": "jpeg",
        "image_quality": 85,
    },
    timeout=120,
)
if not response.ok:
    raise SystemExit(response.json()["error_message"])

with open("eiffel.jpg", "wb") as f:
    f.write(response.content)
print("Saved eiffel.jpg")Saved eiffel.jpg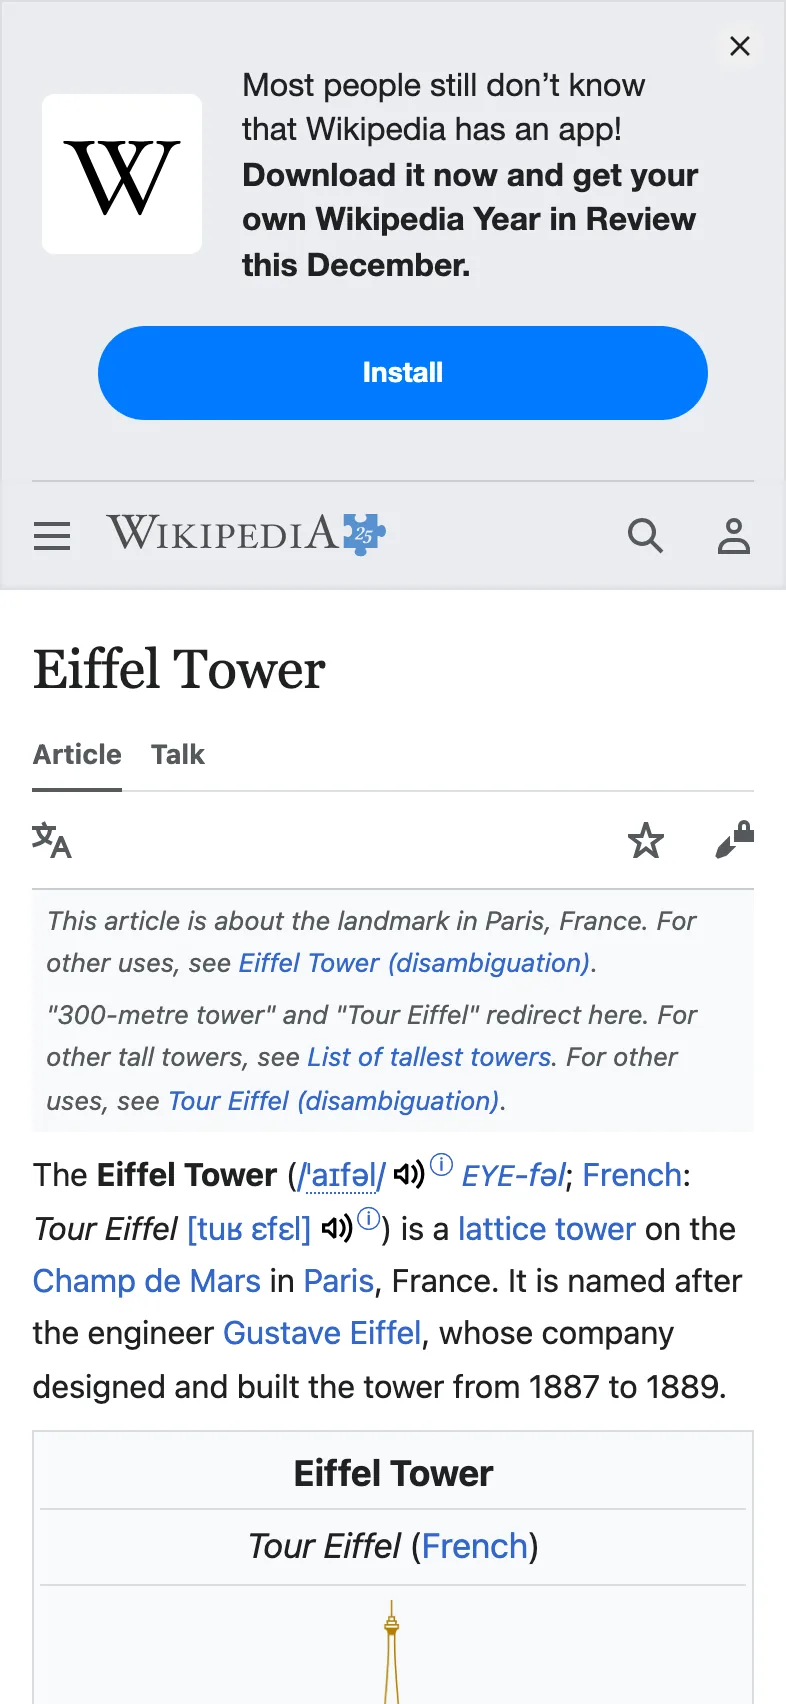
Option names must match exactly. An unknown name, such as fullpage for full_page, is rejected with invalid_options and a hint. Every option is explained in the options reference.
#Render your own HTML with POST
To turn your own HTML into an image, send the options as a JSON body in a POST request. See HTML and Markdown input.
import requests

html = """
<body style="margin:0;display:grid;place-items:center;height:100vh;
             font:700 64px sans-serif;background:#0f172a;color:#fff">
  Hello from HTML
</body>
"""

response = requests.post(
    "https://curlshot.com/api/v1/screenshot",
    headers={"X-Access-Key": "YOUR_ACCESS_KEY"},
    # json= sends a JSON body and sets the Content-Type header for you.
    # In a JSON body, booleans and numbers are real values, not text.
    json={"html": html, "viewport_width": 1200, "viewport_height": 630, "format": "png"},
    timeout=120,
)
if not response.ok:
    raise SystemExit(response.json()["error_message"])

with open("card.png", "wb") as f:
    f.write(response.content)
print("Saved card.png")Saved card.pngYou get card.png, 1200 by 630 pixels: white text centered on a dark background.
#Get JSON instead of the file
With response_type=json the answer is a small JSON document: details about the render and a link to the stored file.
import requests

response = requests.get(
    "https://curlshot.com/api/v1/screenshot",
    headers={"X-Access-Key": "YOUR_ACCESS_KEY"},
    params={"url": "https://news.ycombinator.com", "response_type": "json"},
    timeout=120,
)
result = response.json()
if not response.ok:
    raise SystemExit(result["error_message"])

for name, value in result.items():
print(f"{name}: {value}")id: a187741109b34d6c991bdab9b2c5da03
url: https://curlshot.com/api/v1/files/a187741109b34d6c991bdab9b2c5da03.png?expires=1791155483&token=wr0Y6nTqXC-yLpWGbch_RVMyZqjGaUgnu2Eeq-shclg
format: png
width: 1280
height: 1024
bytes: 265066
render_ms: 1464
cached: False
expires_at: 2026-10-04T23:11:23.563ZThe url needs no access key, so you can hand it to a browser or to another service. It stops working at the time in expires_at, so download the file before then if you need to keep it.
#Handle errors and retry
A failed request returns JSON with an error_code and an error_message, not an image. Some codes are temporary and worth a second try. The rest fail the same way until you change the request. This helper retries the temporary ones and waits a little longer each time.
import time

import requests

API = "https://curlshot.com/api/v1/screenshot"
ACCESS_KEY = "YOUR_ACCESS_KEY"

# Temporary problems. Everything else needs a change to the request.
RETRYABLE = {
    "renderer_busy",
    "renderer_unavailable",
    "service_unavailable",
    "internal_error",
    "timeout",
    "navigation_failed",
    "rate_limited",
    "concurrency_limit",
}


class ScreenshotError(Exception):
    def __init__(self, status, code, message):
        super().__init__(f"{code}: {message}")
        self.status = status
        self.code = code


def take_screenshot(options, tries=4):
    for attempt in range(1, tries + 1):
        response = requests.get(
            API,
            headers={"X-Access-Key": ACCESS_KEY},
            params=options,
            timeout=120,
        )
        if response.ok:
            return response.content

        try:
            body = response.json()
            error = ScreenshotError(response.status_code, body["error_code"], body["error_message"])
        except (ValueError, KeyError):
            # The body is not the JSON we expect. Treat it as a temporary failure.
            error = ScreenshotError(response.status_code, "internal_error", "Unexpected answer")

        if error.code not in RETRYABLE or attempt == tries:
            raise error

        # Use Retry-After when the API sends it. Otherwise wait 1, 2, 4 seconds.
        seconds = int(response.headers.get("Retry-After") or 2 ** (attempt - 1))
        print(f"Attempt {attempt} failed ({error.code}). Waiting {seconds}s.")
        time.sleep(seconds)


try:
    image = take_screenshot({"url": "https://github.com/microsoft/playwright"})
    with open("playwright.png", "wb") as f:
        f.write(image)
    print("Saved playwright.png")
except ScreenshotError as error:
raise SystemExit(f"Gave up: {error}")Attempt 1 failed (renderer_busy). Waiting 1s.
Saved playwright.pngGave up: invalid_options: url: must be a full URL starting with http:// or https://When the API knows how long to wait, it says so in the Retry-After header, in seconds. The errors page lists every code and says which ones can be retried.
#Create a signed link
A signed link is a screenshot address with a signature at the end. It is safe to show in a web page, because nobody can change it without your secret key. Build it on your server.
The signature is an HMAC-SHA256, a checksum made with your secret key, of the sorted and encoded parameters.
import hashlib
import hmac
import time
from urllib.parse import quote


def signed_link(endpoint, params, secret_key):
    # Every parameter, sorted by name, then by value.
    pairs = sorted((str(name), str(value)) for name, value in params.items())
    # safe="" gives strict percent-encoding: a space becomes %20, a slash becomes %2F.
    canonical = "&".join(f"{quote(name, safe='')}={quote(value, safe='')}" for name, value in pairs)
    signature = hmac.new(secret_key.encode(), canonical.encode(), hashlib.sha256).hexdigest()
    return f"{endpoint}?{canonical}&signature={signature}"


link = signed_link(
    "https://curlshot.com/api/v1/screenshot",
    {
        "access_key": "YOUR_ACCESS_KEY",
        "url": "https://en.wikipedia.org/wiki/Eiffel_Tower",
        "format": "webp",
        "viewport_width": 1280,
        "cache": "true",
        # Optional: the link stops working at this time, in Unix seconds. Here: one hour from now.
        "expires": int(time.time()) + 3600,
    },
    "YOUR_SECRET_KEY",
)
print(link)https://curlshot.com/api/v1/screenshot?access_key=YOUR_ACCESS_KEY&cache=true&expires=1791159083&format=webp&url=https%3A%2F%2Fen.wikipedia.org%2Fwiki%2FEiffel_Tower&viewport_width=1280&signature=6c5f73bd40f701699781ec1faf569d8c164f5936c823d1c2a293fa1ff9170e7eexpires is optional. It is a Unix time, the number of seconds since 1970. The link works until that time and never after: the API then answers 403 request_expired. It is part of the signed text, so nobody can move it. Leave it out for a link that never expires.
To test your signing code, keep the placeholder keys and leave out expires. The signature must then be b565e2249494a979e38a79a4c9556b316ff64f15df96febf44c69b9709a52213.
#Run a render in the background and poll
With async=true the API answers at once with a job, and the render runs in the background. You then poll: ask the job address every two seconds until the job is done or failed. More on this in Async and webhooks.
import time

import requests

headers = {"X-Access-Key": "YOUR_ACCESS_KEY"}

# 1. Start the job.
started = requests.get(
    "https://curlshot.com/api/v1/screenshot",
    headers=headers,
    params={
        "url": "https://en.wikipedia.org/wiki/Eiffel_Tower",
        "full_page": "true",
        "async": "true",
    },
    timeout=30,
)
started_body = started.json()
if not started.ok:
    raise SystemExit(started_body["error_message"])
print("Started", started_body["job_id"])

# 2. Ask every two seconds until the job is done or has failed. Give up after two minutes.
job = None
for _ in range(60):
    time.sleep(2)
    response = requests.get(started_body["job_url"], headers=headers, timeout=30)
    job = response.json()
    if not response.ok:
        raise SystemExit(job["error_message"])
    print("Status:", job["status"])
    if job["status"] in ("done", "failed"):
        break

if job is None or job["status"] not in ("done", "failed"):
    raise SystemExit("The job did not finish in time")
if job["status"] == "failed":
    raise SystemExit(f"{job['error_code']}: {job['error_message']}")

# 3. Download the finished file from the link in the job.
file = requests.get(job["screenshot"]["url"], timeout=120)
file.raise_for_status()
with open("eiffel-full.png", "wb") as f:
    f.write(file.content)
print("Saved eiffel-full.png,", job["screenshot"]["bytes"], "bytes")Started job_917e1044a2a8885401dae084
Status: processing
Status: done
Saved eiffel-full.png, 7373357 bytes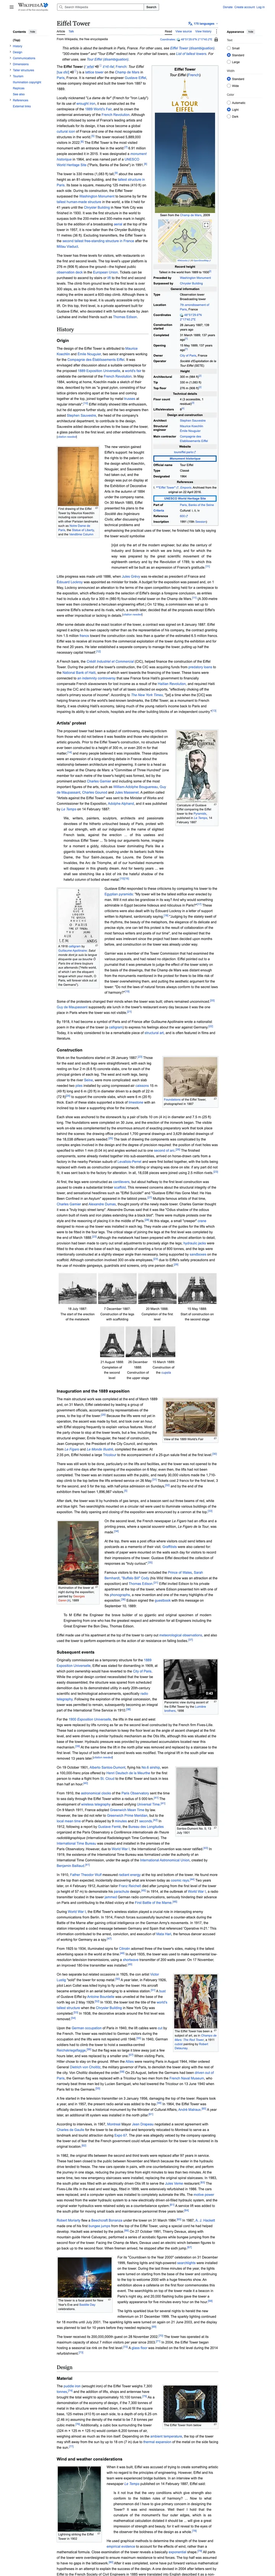
A finished job holds the result in screenshot, which is null until then. A failed job holds an error_code and an error_message instead.
Asking for the status does not use your quota. The file link in screenshot.url needs no access key and works until the job's screenshot.expires_at.
#Where to go next
- Options reference: every option you can put in
params. - Errors: every error code with its cause and fix.
- Signed links: the signing steps explained one by one.
- Async and webhooks: get a call when the job ends, with no polling.
- PHP examples: the same tasks in PHP.